This September, two developments that caught my attention – which seemed counter intuitive.
Mastercard published The new economics of AI, a detailed white paper arguing that AI’s variable cost is the problem most enterprises haven’t solved. Unpredictable model token costs from employees, agents that can bloat the usage significantly, and badly designed products make most Agentic AI initiatives unprofitable by design. Why is a payment processor coming out with such detailed analysis on token pricing, AI business models is probably a separate article in itself.
However very recently, a start-up called TypeSafe released Jev, a model that can’t write a word. It only decides: pick an option, give a score, answer yes or no, each with a confidence number, at roughly a hundredth of the cost of a typical LLM call. Developers adopted it almost overnight.
While one says that AI is too expensive the other says AI decisioning is damn cheap. I feel both are kind of right and together they point to something neither says on its own.
Cheaper decisions don’t necessary mean cheaper outcomes
Jev is named after William Stanley Jevons, the 19th-century economist who noticed that more efficient steam engines didn’t reduce coal consumption. They increased it, because cheaper energy found many more uses. The same is about to happen to machine decisions. When routing a ticket, flagging an invoice or approving a step costs a fraction of a cent and takes a tenth of a second, organizations won’t be in a position to realize those gains unfortunately. More automations will take a major slice of that freed up budget. The Mastercard paper hints at this too: citing Gartner, it expects total inference spend to rise even as unit costs fall.
So, cost savings do matter, but it might be a temporary advantage. Unit costs will keep falling for everyone. What doesn’t fall is the cost of a wrong decision: a wrongly approved payment, a misrouted complaint, a missed fraud. As decision volume explodes, the otherwise one off wrong decision logic get violated.
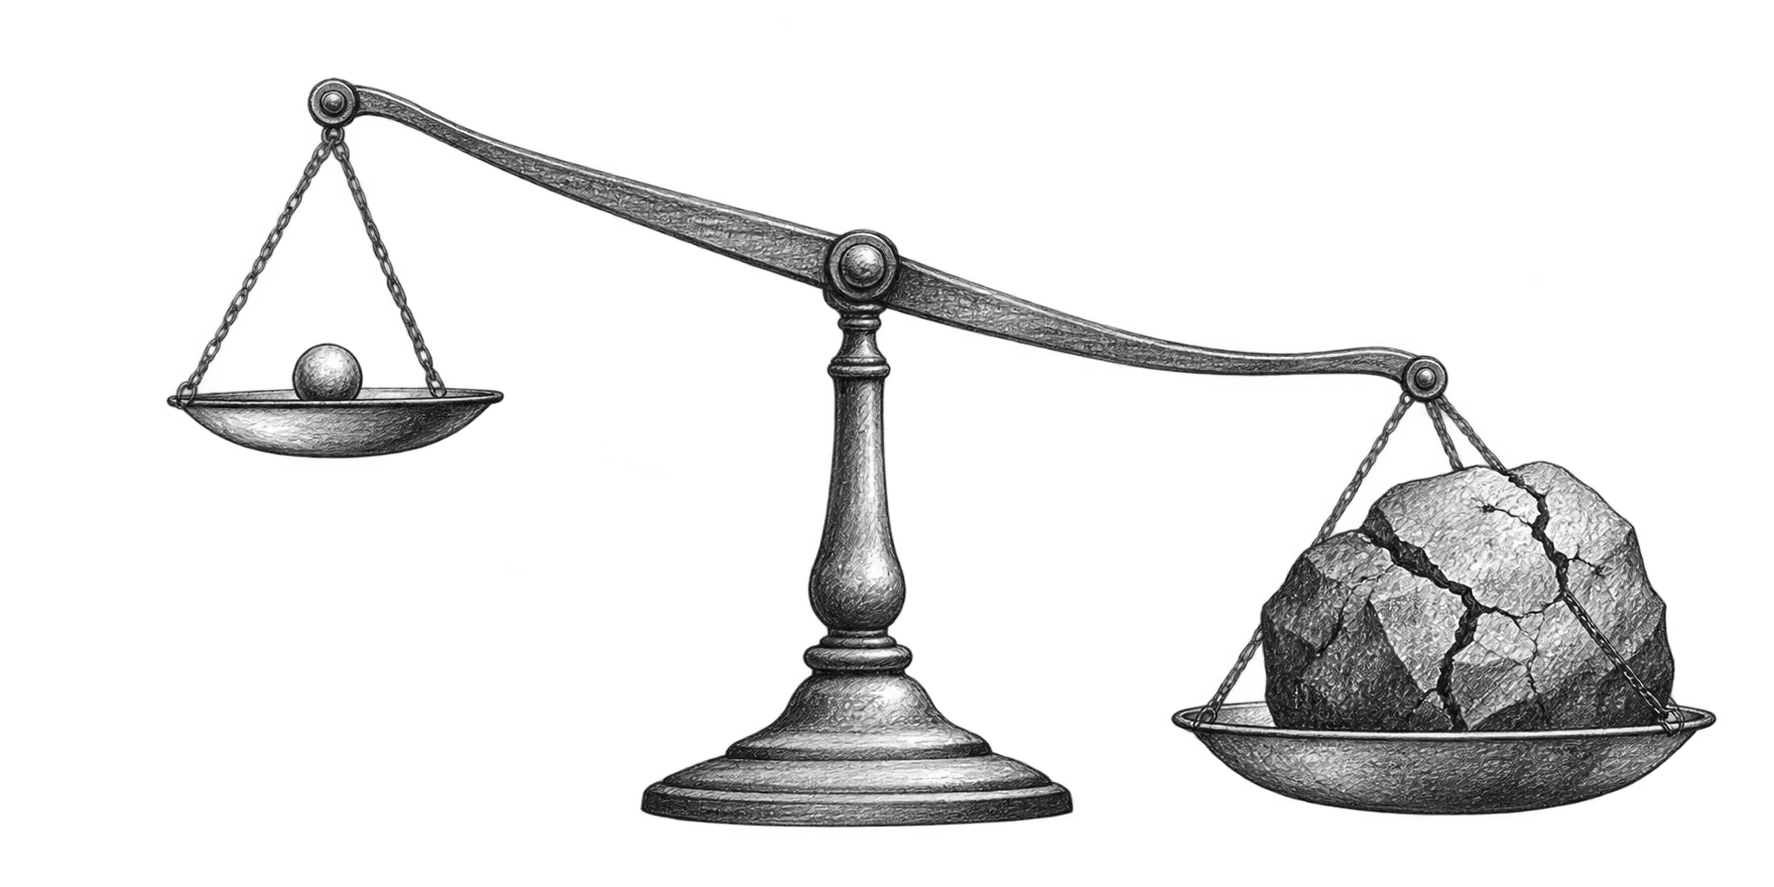
The price of an AI decision is collapsing. The cost of a wrong one isn’t.
Making machine decisions safely at scale means working with probabilities: automate when the model is confident, send uncertain cases to a person, and know how often “confident” is actually right.
Technically, this is now easy. Decision models return confidence scores out of the box, and an engineer can wire a threshold into a workflow in an afternoon. But sadly, most enterprises aren’t ready organizationally. Three gaps stand out:
Scores need checking. A 90% confidence score is useful only if the model is right about 90% of the time at that level. Even Jev’s calibration has been disputed by independent testing. Every threshold must be validated on your own data.
• Ground truth is missing. Most of the time, human decisions were rarely recorded with their outcomes. There is a huge bank of tacit knowledge that is still undocumented.
• Nobody owns the cut-off. Where to set a threshold is a risk-appetite call, not an engineering one. It falls between IT, the business and risk, so often nobody sets it deliberately.
Yet some parts of the enterprise have worked this way for decades. Banks set cut-offs on credit scores; card issuers do the same for fraud, and insurers for claims triage. Those teams treat thresholds as policy, monitor drift and staff exception queues. Probabilistic decision-making isn’t new to enterprises but is harder to enforce as it needs cross departmental expertise and collaboration.
Where to start: three experiments
1. Map a handful of decisions and build their ground truth. Pick three to five high-volume decisions with fixed answers and a clear cost of error. Collect past decisions, outcomes and human corrections. That labelled history outlasts any model, and no vendor can sell it to you.
2. Run in shadow, then set thresholds by the cost of being wrong. Let the AI decide alongside people without acting, and compare a frontier model, a decision model and a small open model on the same cases. Then automate the confident cases, route the uncertain middle to people and escalate the rest. A misrouted ticket and a wrongly approved payment deserve very different cut-offs.
3. Log every decision and recalibrate. Record the input, score, action and outcome. This is your audit trail and your recalibration data. Thresholds that were right in March may be wrong by September.
Are you ready to give that authority to the machine though?
A company making a thousand AI decisions a day can review them with humans. As the numbers rise, this is not practical and hence the model has to make some decisions. Moreover, in the future (maybe not that distant), especially once agents start acting for each other across company boundaries, the question changes from capability to accountability. Who gave it the authority, within what limits, and who answers when it’s wrong?
Tellingly, the payments industry is already building answers: verified agent identities, spending limits, audit trails and dispute processes for machine-initiated transactions. In a later article, I’ll look at what enterprises can borrow from an industry that has spent decades making strangers trust each other.